A Clear Path to Faster AMR Wins
Picture a late-shift warehouse: aisles busy, pallets waiting, operators checking screens. Throughput sinks as the clock ticks. That outcome hinges on your amr controller — in many cases, an industrial robotic amr controller that sits between perception and motion. Here’s the technical bit: the controller coordinates sensor fusion, plans paths, and schedules tasks across the fleet. Small change there, big effect here (funny how often that’s true). In field deployments, idle time can rise 18–25% when dispatch logic lags, while battery swaps can jump 12% with poor energy policies. So the question is simple: what unlocks faster, safer routes with the same hardware and people?
Let’s move from the floor to the control stack and see what truly separates steady results from stop‑and‑go chaos. We’ll compare where teams get stuck and where smarter decisions lift the whole operation. Then we’ll line up the principles that future‑ready systems use to outpace the old guard—without asking you to rip and replace.
The Hidden Friction Behind Slow Fleets
Where do old stacks stumble?
Legacy designs often tie real‑time motion to a single CPU path, while fleet orchestration sits somewhere “above” it, as if the two barely talk. That gap adds jitter. When CAN bus traffic, LiDAR bursts, and camera frames hit at once, the loop time spikes, and the robot hesitates. You feel it as a pause in a tight aisle. Operators call it a “glitch.” It’s not. It’s an architecture issue. Without clear QoS in the middleware and predictable timing, SLAM updates collide with path planning. Add power converters that throttle under peak draw, and you get slow starts after every stop — funny how that works, right?
There’s more, and it’s quieter. Mixed vendors mean drivers for lifts, carts, and grippers update at different rates. Edge computing nodes run one version of ROS 2, the supervisor another. Your safety PLC is rock‑solid, but it forces conservative speeds because the controller can’t prove margins. This is why “just tune the parameters” so often fails. Look, it’s simpler than you think: you need a controller that treats timing as a first‑class feature, not a best effort. It should align SLAM, motion control, and energy policies under one predictable cycle. It should expose clean hooks for batteries, chargers, and traffic rules so the fleet doesn’t trip over itself during rush hour.
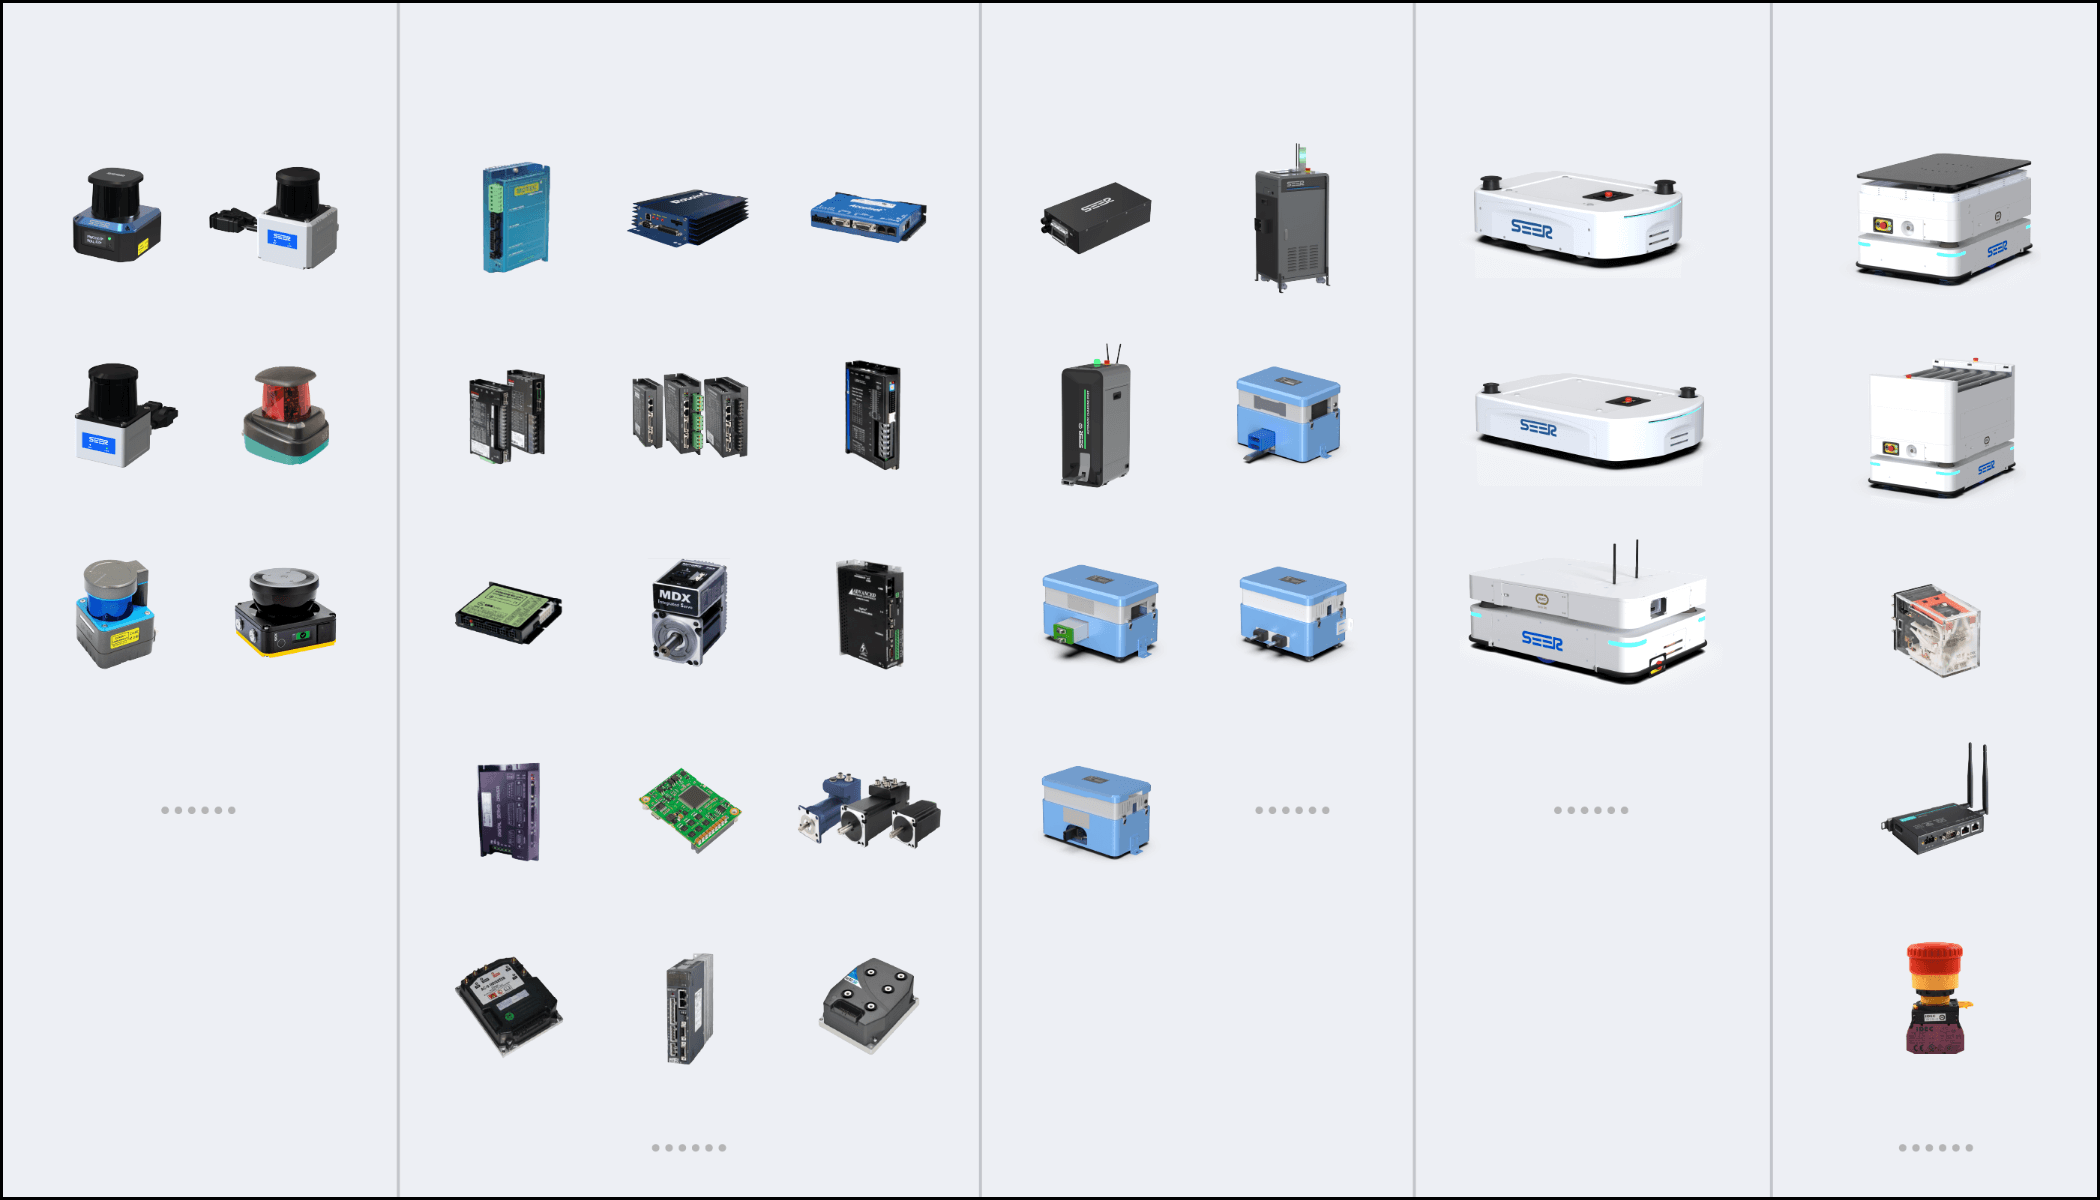
From Patchwork to Principles: A Smarter Controller Playbook
What’s Next
Now flip the view to a forward‑looking stack. A modern industrial robotic amr controller uses new principles that cut delay at the source. Time‑sensitive networking (TSN) and deterministic middleware keep message timing tight. Model‑predictive control adjusts velocity and clearance on the fly, rather than toggling canned profiles. Fleet orchestration runs close to the floor on edge computing nodes, so tasks reach bots in milliseconds, not seconds. Energy is no afterthought: the controller schedules jobs with battery state in mind and blends braking recovery with charger queues. Add driver coverage for CAN bus, EtherCAT, and Modbus, and your mixed fleet looks like one system, not a set of silos. The result is a calmer loop, fewer pauses, and straighter lines. It feels boring in the best way — stable, repeatable, fast.
Compared with the old patchwork, the difference is measurable. You trim 99.9th‑percentile loop time, not just the average. You limit SLAM regressions by pinning compute budgets per node. You keep safety margins but prove them in software, so the PLC doesn’t force blanket slowdowns. Over‑the‑air updates let you ship small changes often, which reduces risky “big‑bang” upgrades. And yes, the controller still plays nice with existing lifts and power converters; it just does so with clear timing contracts and health checks. In short, you trade surprise for certainty, and certainty for speed. That’s the real win.
To choose well, lean on three practical metrics: 1) Determinism under load: track 99.9th‑percentile control‑loop latency and packet jitter during worst‑case sensor fusion bursts. 2) Integration depth: verify native drivers and safety support across your devices (CAN bus, EtherCAT, Modbus, and safety PLCs) plus clean APIs for charging and traffic rules. 3) Fleet ROI signals: measure orders per hour per robot, kWh per task, and time‑to‑recover after a fault. If a controller improves all three in a pilot, you have your direction — and a calmer team, too. For a deeper look at controller design done with these principles in mind, see SEER Robotics.